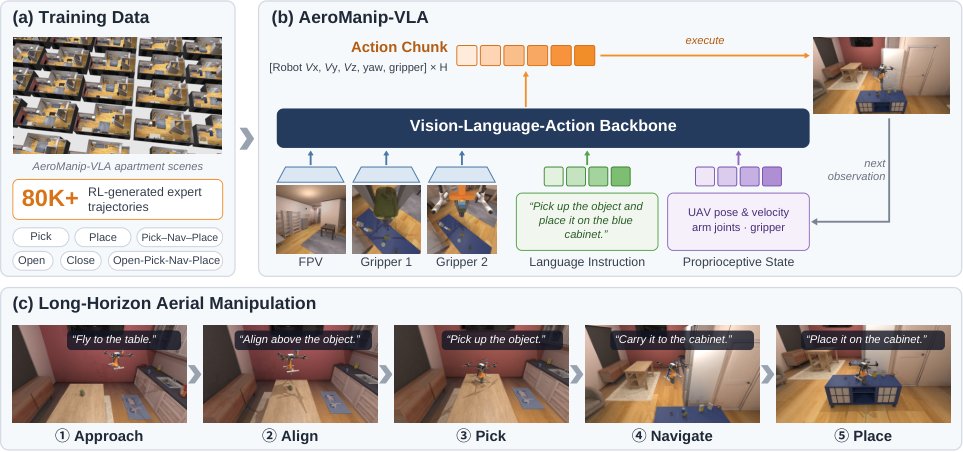
作者:Rui Huang, Yanlin Mu, Lidong Li, Yucong Wang, Zichen Yan, Lin Zhao · 单位:National University of Singapore, Beijing Institute of Technology · 会议/期刊:arXiv preprint · 方向:cs.RO · 发布日期:2026-09-30
点击后会加入生成队列