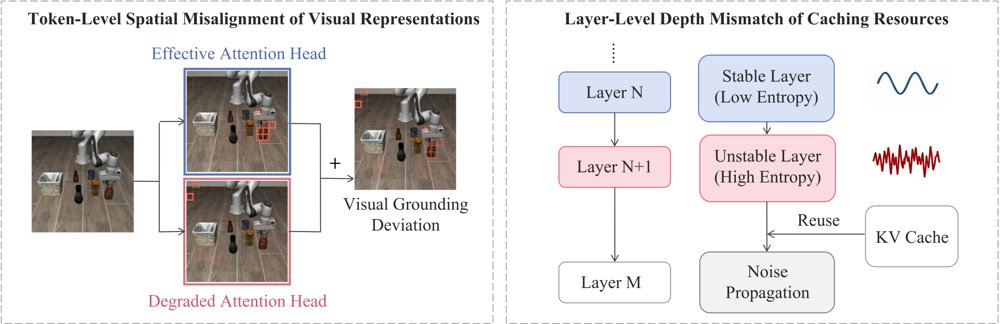
Text-Vision Synergistic Token Caching: A Training-Free Framework for Efficient Vision-Language-Action Inference
作者:Qianer Li, Chengjie Zhang, Jingwen Chen, Zanjia Tong, Jiyuan Zhang, Hong Zhang · 单位:Jiyuan Zhang is with the Master of Science in Data Science and Ma- chine Learning , Department of Mathematics, Faculty of Science, National University of Singapore, Singapore. · 会议/期刊:arXiv preprint · 方向:cs.CV · 发布日期:2026-09-29