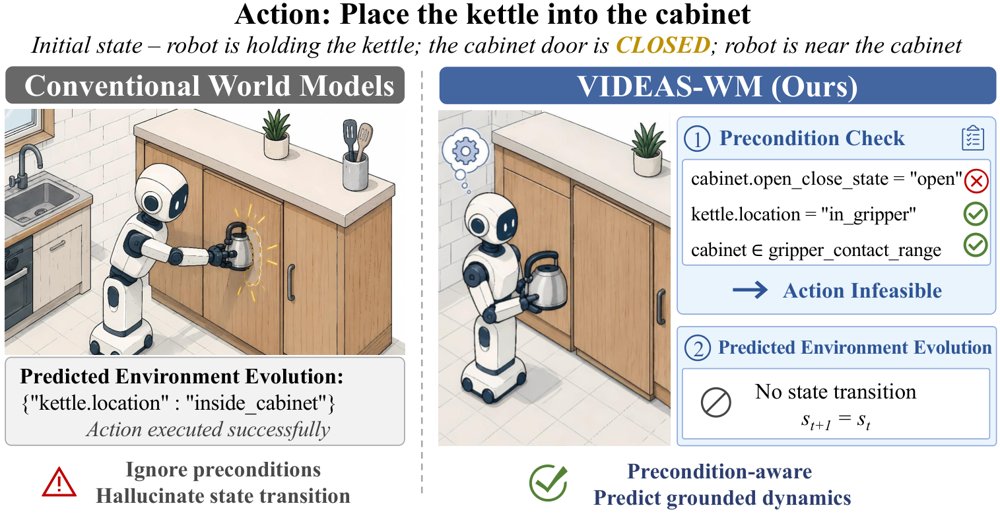
VIDEAS: Distilling Explicit Action Semantics from Demonstration Videos for World Models via Prior-Guided Simulation
作者:Jianan Wang, Haoquan Zhai, Siyang Zhang, Bin Li, Juan Chen, Jingtao Qi, Zhuo Zhang, Enze Wang, Haoxiang Jin, Chen Qian · 单位:College of Computer Science and Technology, National University of Defense Technology, School of Electronic, Electrical and Communication Engineering, University of Chinese Academy of, Intelligent Game and Decision Lab (IGDL), School of Artificial Intelligence, Shanghai Jiao Tong University * Corresponding authors · 会议/期刊:arXiv preprint · 方向:cs.RO · 发布日期:2026-09-29