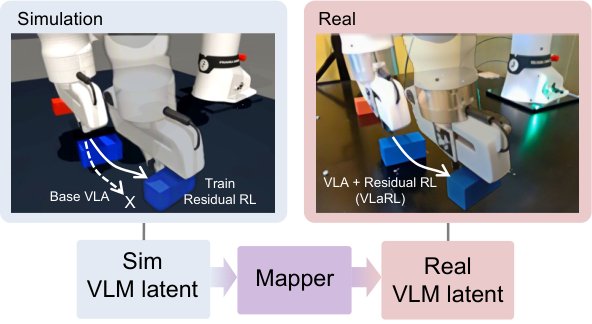
VLaRL: Augmenting Vision-Language-Action Models with Simulation-Trained Latent-Conditioned Residual RL
作者:Namiko Saito, Kinam Kim, Heecheol Kim, Katsushi Ikeuchi, Yasuyuki Matsushita · 单位:$ˆ3$Katsushi Ikeuchi is also with The University of Tokyo, Japan. · 会议/期刊:arXiv preprint · 方向:cs.RO · 发布日期:2026-09-28